Fireworks DeepSeek V4.1 Flash review: stop requests return empty body, 8k cache hot requests hit 3 of 9
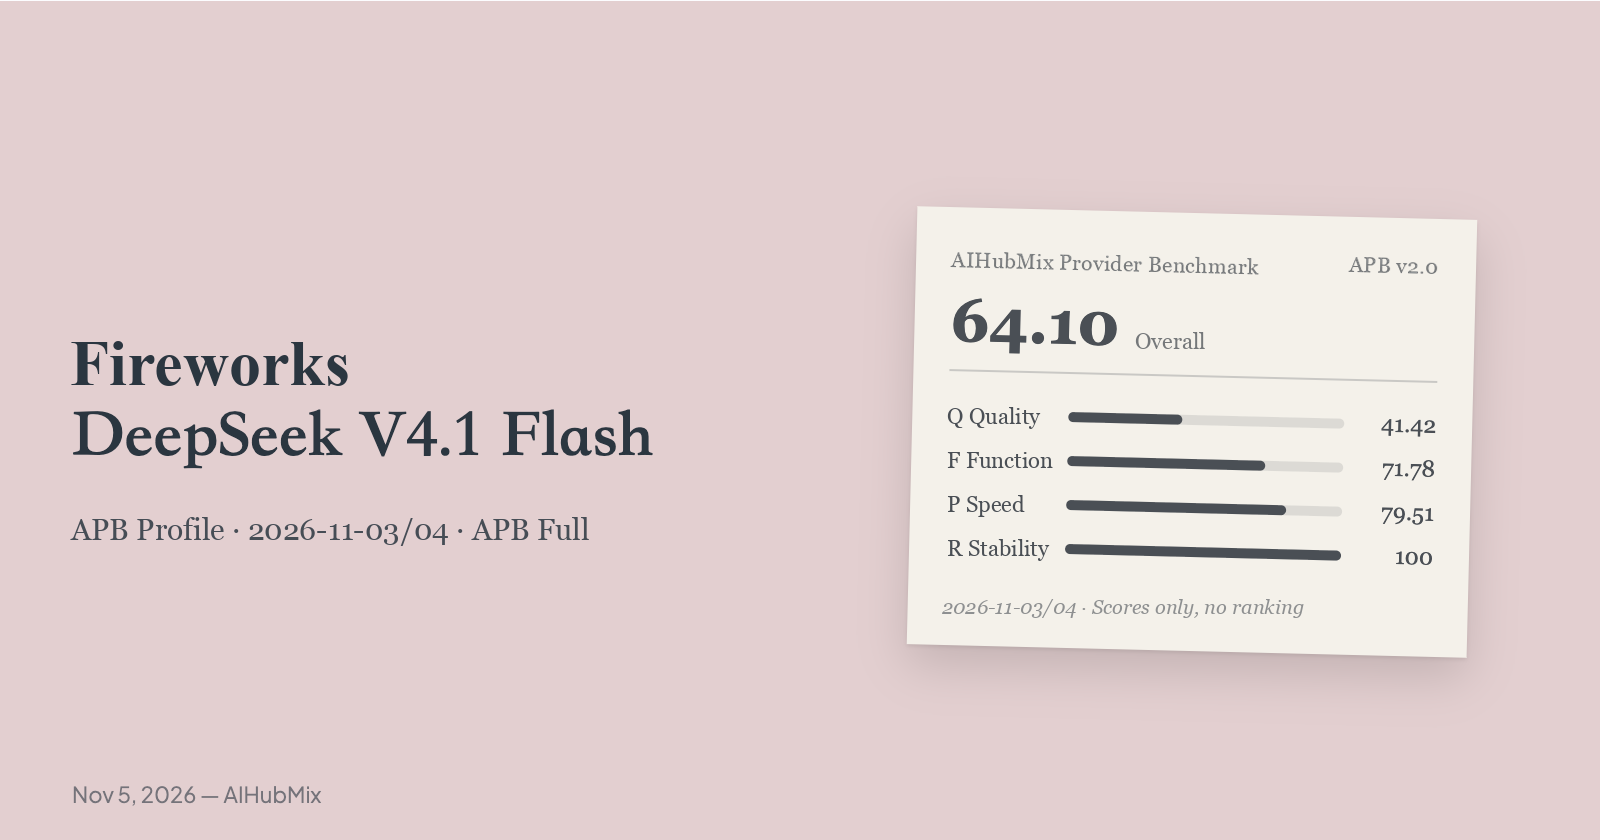
In the 2026-11-03/04 APB Full run, Fireworks' Q is 41.42, and the 95% interval of its gap to the official channel includes 0. F is 71.78: requests with a stop sequence returned an empty body, the APB v2 parameter-contract check failed, and reported input tokens do not match the native count. K is 60.68.
On 2026-11-03/04, DeepSeek V4.1 Flash 1017 was tested on six providers through AIHubMix with the APB Full suite, using the same questions, parameters and request scripts for each. This APB Profile covers Fireworks only: what each section measured and how it came out.
The numbers below are scores, not a ranking or a provider recommendation. The four scores, Q, F, P and R, come first; the overall is a summary index, not a certification, and it has no confidence interval. The scoring rules are defined in AIHubMix Provider Benchmark Standard v2.0.
Scores across six providers
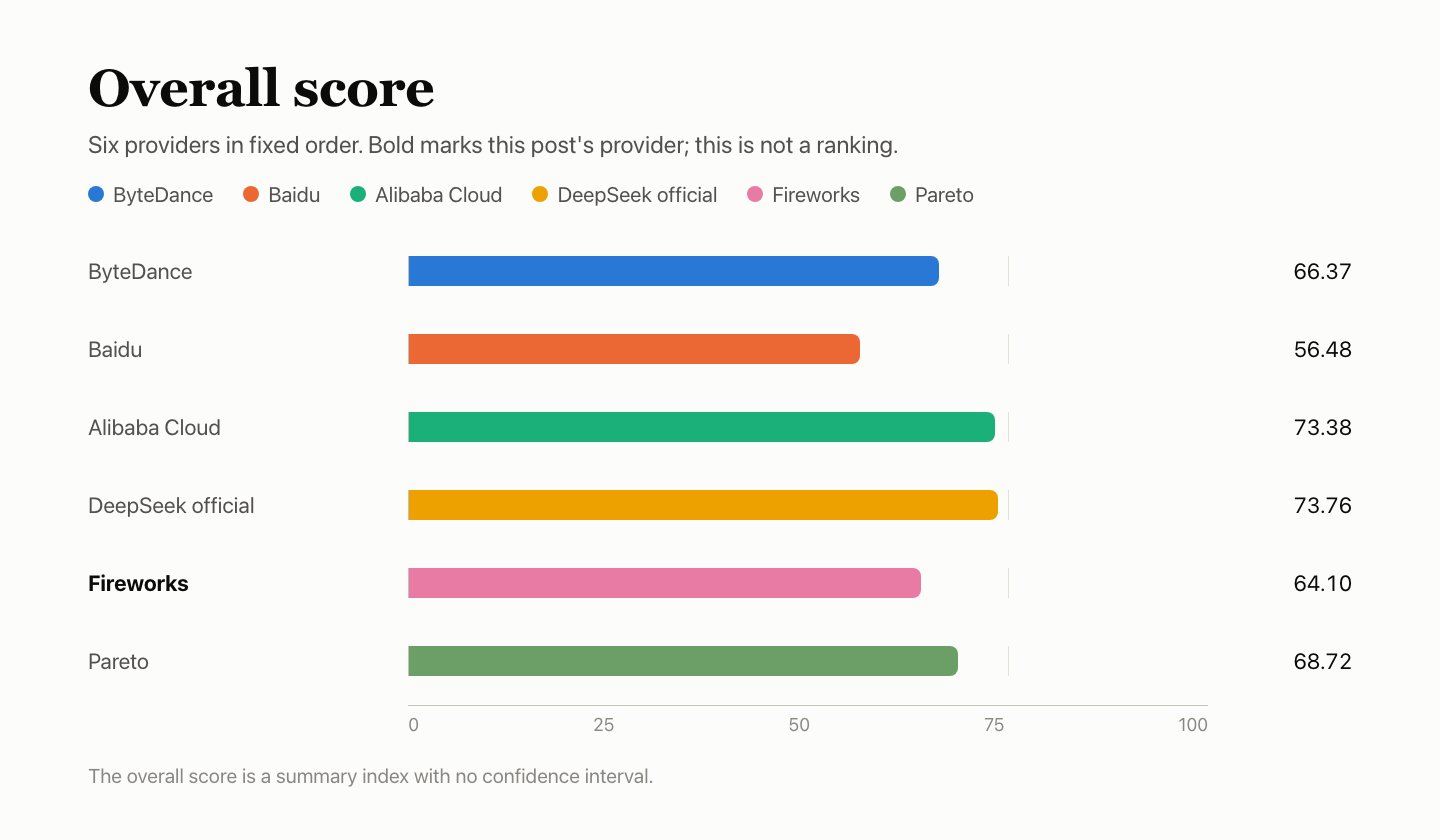
| Provider | Q quality | F function | P speed | K cache | R stability | Overall |
|---|---|---|---|---|---|---|
| ByteDance | 42.05 | 74.98 | 84.37 | 93.83 | 100 | 66.37 |
| Baidu | 38.00 | 88.39 | 37.77 | 68.85 | 100 | 56.48 |
| Alibaba Cloud | 41.75 | 89.78 | 88.58 | 99.37 | 100 | 73.38 |
| DeepSeek official channel | 42.45 | 94.00 | 86.14 | 98.38 | 100 | 73.76 |
| Fireworks (this post) | 41.42 | 71.78 | 79.51 | 60.68 | 100 | 64.10 |
| Pareto | 44.58 | 93.42 | 57.69 | 27.58 | 100 | 68.72 |
Providers are listed in a fixed order, not a ranking. K is a sub-score of P, accounting for 20% of it, and is listed separately for reference. The overall score is computed with the composition rules of AIHubMix Provider Benchmark Standard, which also take in the comparison with the official channel and evidence completeness; it is not a direct weighting of the four scores in the table. It is a summary index with no confidence interval. The DeepSeek official channel and Alibaba Cloud differ by only 0.37 overall, which is not a distinguishable difference.
At a glance
- Answer quality: Q 41.42, with BFCL 85.53%, HLE 14.38% and AA-LCR 46.00%. The gap to the official channel is −1.04 percentage points, with a 95% interval of −2.14 to +0.05: not distinguishable. AA-LCR had 34 request failures, all in window 2, counted as wrong.
- Function support: F 71.78; 122 of 177 counted checks passed. Both stop cases returned an empty body; the APB v2 parameter-contract check failed; a 10k input was reported as 10,026 tokens (native count 10,000).
- Response speed: P 79.51, from a response score of 84.22 with cache K at 20%. Median first body token 1.63 s at single concurrency and 1.64 s at 10-way, TPOT 3.29 ms; 1 of 180 speed requests returned a 1-token body and was counted invalid.
- Cache: K 60.68. Cache requests carried the session-affinity parameters from Fireworks' documentation; 32k hot requests hit 8 of 9, 8k only 3.
- Service stability: R 100. All 300 dedicated requests succeeded on the first attempt.
Test setup
| Item | Detail |
|---|---|
| Model | DeepSeek V4.1 Flash 1017 |
| Requested model ID | fireworks-deepseek-v4.1-flash-1017 |
| Returned model name | accounts/fireworks/models/deepseek-v4p1-flash-1017 |
| Access route | Through AIHubMix with a provider-specific model ID, not a direct connection to the provider's account |
| Parameters | Fixed APB v2 request profile, temperature 1.0, max_tokens 16,384, 300 s timeout, no automatic retry |
| Test profile | The five providers other than Pareto shared one fixed APB v2 profile for Q/P/K/R; F also checked its parameter contract |
| Cache requests | As Fireworks' documentation requires, sent with a user field and an x-session-affinity header so requests with the same prefix land on the same replica |
| Time | 2026-11-03 18:07 – 11-04 16:33; cache requests 11-04 23:49 – 11-05 00:06; all UTC+8. All six providers shared one Mac mini, one network and one account. |
| Samples | Q 4,250 question-instances; F 180 checks; P 180 requests; R 300; K 30 |
Requests used the AIHubMix quick start route with a provider-specific model ID; the other providers' IDs are listed on the models page. The model's own parameters are described in DeepSeek's API documentation.
Q — answer quality: 41.42
Answer quality draws on three suites: 500 BFCL questions answered 3 times each, 250 HLE questions answered 10 times each, and 25 AA-LCR questions answered 10 times each. BFCL is scored by automatic rules; HLE and AA-LCR are judged right or wrong by the judge model deepseek-flash. All six providers received the same questions, and the three suites are pooled into one accuracy. Ten answers were removed because the question could not be scored, leaving 4,240 scored question-instances.
| Suite | Questions × rounds | Correct | Accuracy | Service failures |
|---|---|---|---|---|
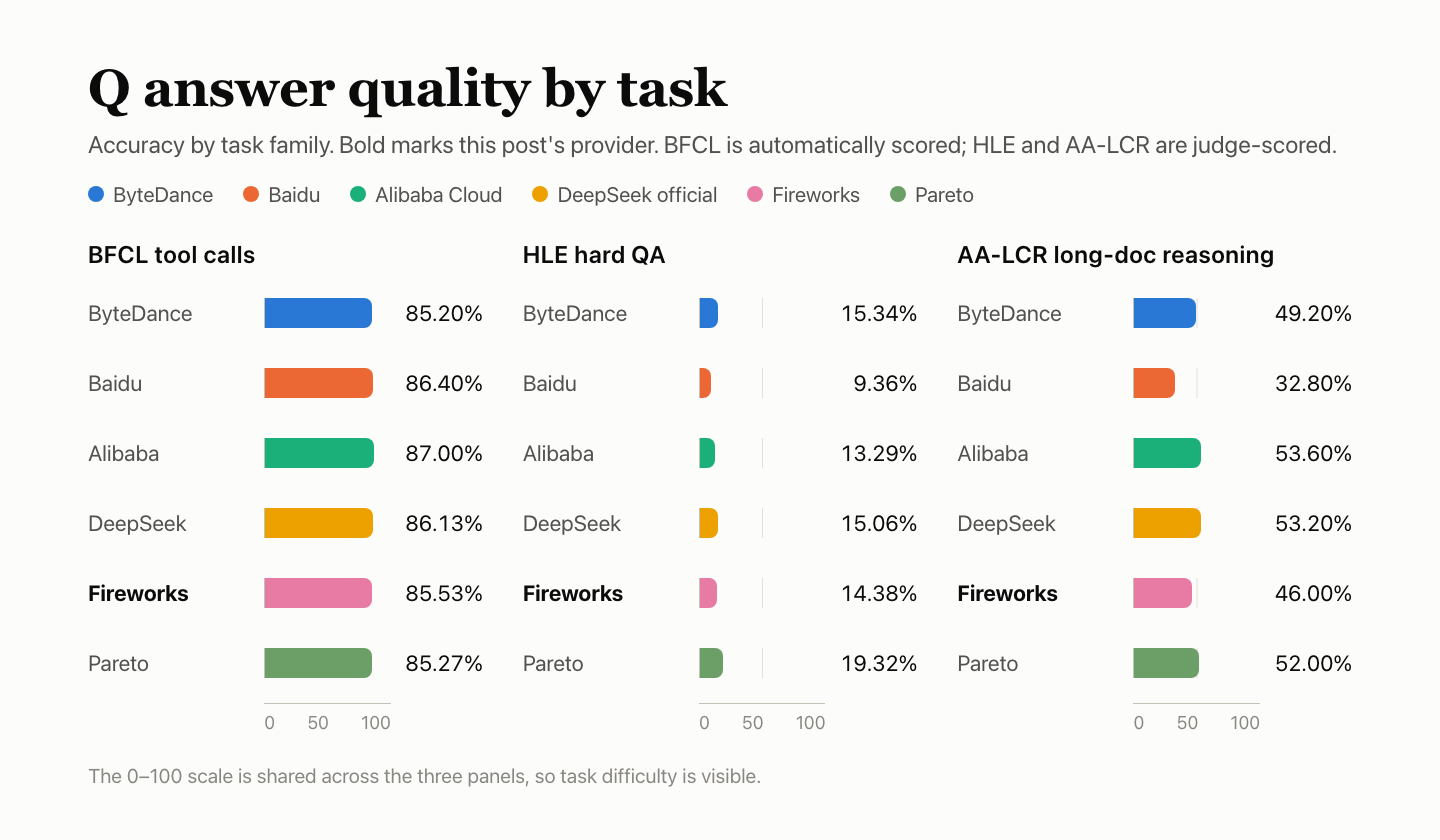
| BFCL tool calls, auto-scored | 500 × 3 | 1,283/1,500 | 85.53% | 2 |
| HLE hard QA, judge-scored | 250 × 10 | 358/2,490 | 14.38% | 5 |
| AA-LCR long-doc reasoning, judge-scored | 25 × 10 | 115/250 | 46.00% | 34 |
| Total · 95% interval 39.13%–43.59% | — | 1,756/4,240 | 41.42% | 41 |
Service failures (failed requests or truncated output) stay in the denominator as wrong answers: BFCL had 2 request failures (1 in window 2, 1 in window 3); HLE output hit the max_tokens ceiling 5 times; AA-LCR had 34 request failures, all in window 2.
| BFCL category | Passed | Pass rate |
|---|---|---|
| simple_python: one function, right call and arguments | 333/360 | 92.50% |
| multiple: pick the right one of several functions | 268/300 | 89.33% |
| parallel: one function called several times at once | 270/300 | 90.00% |
| parallel_multiple: several functions at once | 206/240 | 85.83% |
| irrelevance: no relevant function, so no call | 111/150 | 74.00% |
| ahm_multi_turn: three-stage tool chain | 95/150 | 63.33% |
Each BFCL question was answered 3 times; the table sums the 3 rounds.
Compared with the other five
| Provider | BFCL | HLE | AA-LCR | Combined | Vs official |
|---|---|---|---|---|---|
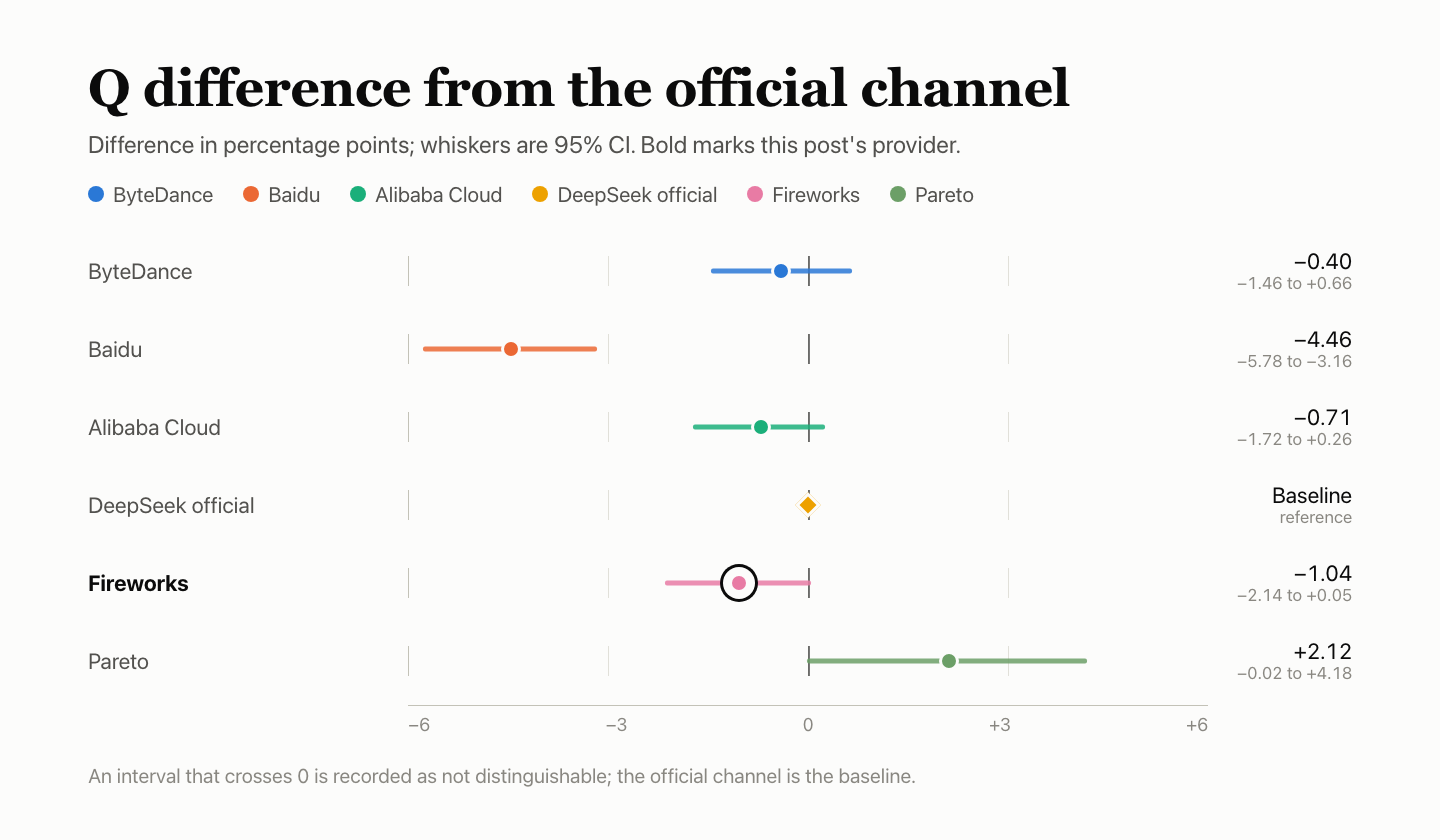
| ByteDance | 85.20% | 15.34% | 49.20% | 42.05% | −0.40 (−1.46 to +0.66), not distinguishable |
| Baidu | 86.40% | 9.36% | 32.80% | 38.00% | −4.46 (−5.78 to −3.16), below official |
| Alibaba Cloud | 87.00% | 13.29% | 53.60% | 41.75% | −0.71 (−1.72 to +0.26), not distinguishable |
| DeepSeek official channel | 86.13% | 15.06% | 53.20% | 42.45% | Baseline |
| Fireworks (this post) | 85.53% | 14.38% | 46.00% | 41.42% | −1.04 (−2.14 to +0.05), not distinguishable |
| Pareto | 85.27% | 19.32% | 52.00% | 44.58% | +2.12 (−0.02 to +4.18), not distinguishable |
Vs official: the accuracy gap in percentage points, with the 95% interval in brackets; an interval that crosses 0 is recorded as not distinguishable. The HLE and AA-LCR judge, deepseek-flash, belongs to the same DeepSeek family as the tested model and was not calibrated, so its judgments may be lenient.
F — function support: 71.78
The function suite looks only at whether interface behaviour matches the protocol, not at whether the model answers well. Sixty cases in six groups ran once in each of three windows: 180 checks, judged against the format each provider documents. Checks that were not applicable, invalid or unobserved leave the denominator. Fireworks passed 122 of 177 counted checks and scored 71.78 on the group weights.
| Case group | Weight | Passed | Excluded | Group score |
|---|---|---|---|---|
| Streaming and message protocol | 20% | 24/30 | — | 80.00 |
| Tool interface | 20% | 29/30 | — | 96.67 |
| Output constraints and parameters | 20% | 21/30 | — | 70.00 |
| Context and state | 15% | 15/30 | — | 50.00 |
| Errors and recovery | 15% | 21/30 | — | 70.00 |
| Metering and cache protocol | 10% | 12/27 | 3 | 44.44 |
| Total · weighted score | — | 122/177 | 3 | 71.78 |
The weighted score applies the group weights; it is not simply passed checks divided by 177.
| Failed case | Windows | Reason |
|---|---|---|
| Streaming stop sequence · streaming and message protocol | 3/3 | Empty body with a stop sequence; the same input without stop worked |
| Reasoning stays out of content · streaming and message protocol | 3/3 | The APB v2 parameter-contract check still returned thinking content |
| Stop sequence · output constraints and parameters | 3/3 | Empty body with a stop sequence; the same input without stop worked |
| Thinking config takes effect · output constraints and parameters | 3/3 | The APB v2 parameter-contract check still returned thinking content |
| Sampling diversity · output constraints and parameters | 3/3 | Outputs at temperature 0 and 1 differed too little for the pre-registered bar |
| 10k long input · context and state | 3/3 | Reported 10,026 input tokens; the native count is 10,000 |
| Within context limit · context and state | 3/3 | Reported 10,026 input tokens; the native count is 10,000 |
| 32k long input · context and state | 3/3 | Reported 10,026 input tokens; the native count is 10,000 |
| 100k long input · context and state | 3/3 | Reported 10,026 input tokens; the native count is 10,000 |
| Over context · context and state | 3/3 | Returned 200 instead of a parameter error |
| Malformed messages · errors and recovery | 3/3 | 400 with an empty body, no structured error |
| Orphan tool result · errors and recovery | 3/3 | Returned 200 instead of a parameter error |
| Malformed stream_options · errors and recovery | 3/3 | 400 with an empty body, no structured error |
| Reasoning-token metering · metering and cache protocol | 3/3 | The APB v2 parameter-contract check still reported reasoning tokens |
| Native input count · metering and cache protocol | 3/3 | Reported 34 input tokens; the native count is 8 |
| Tool definitions counted in input · metering and cache protocol | 3/3 | Even the no-tools control misreported input tokens |
| Input count stable with cache · metering and cache protocol | 3/3 | With a repeated prefix, reported input tokens missed the native count |
| Streaming vs non-streaming input · metering and cache protocol | 3/3 | Streaming and non-streaming both reported 34; native count is 8 |
| One call at a time · tool interface | 1/3 | Upstream returned 500 |
“Windows” is how many of the 3 windows failed the check.
| Status | Case | Count | Reason |
|---|---|---|---|
| Not applicable | Explicit cache_control | 3 | Registered in advance as unsupported by this interface |
These checks leave the denominator; they count as neither a pass nor a failure.
The malformed-messages and malformed-stream-options error cases failed on several providers: they returned 400 with an empty body, so the client gets no structured error explanation. Reasoning-token metering behaved differently from provider to provider.
Compared with the other five
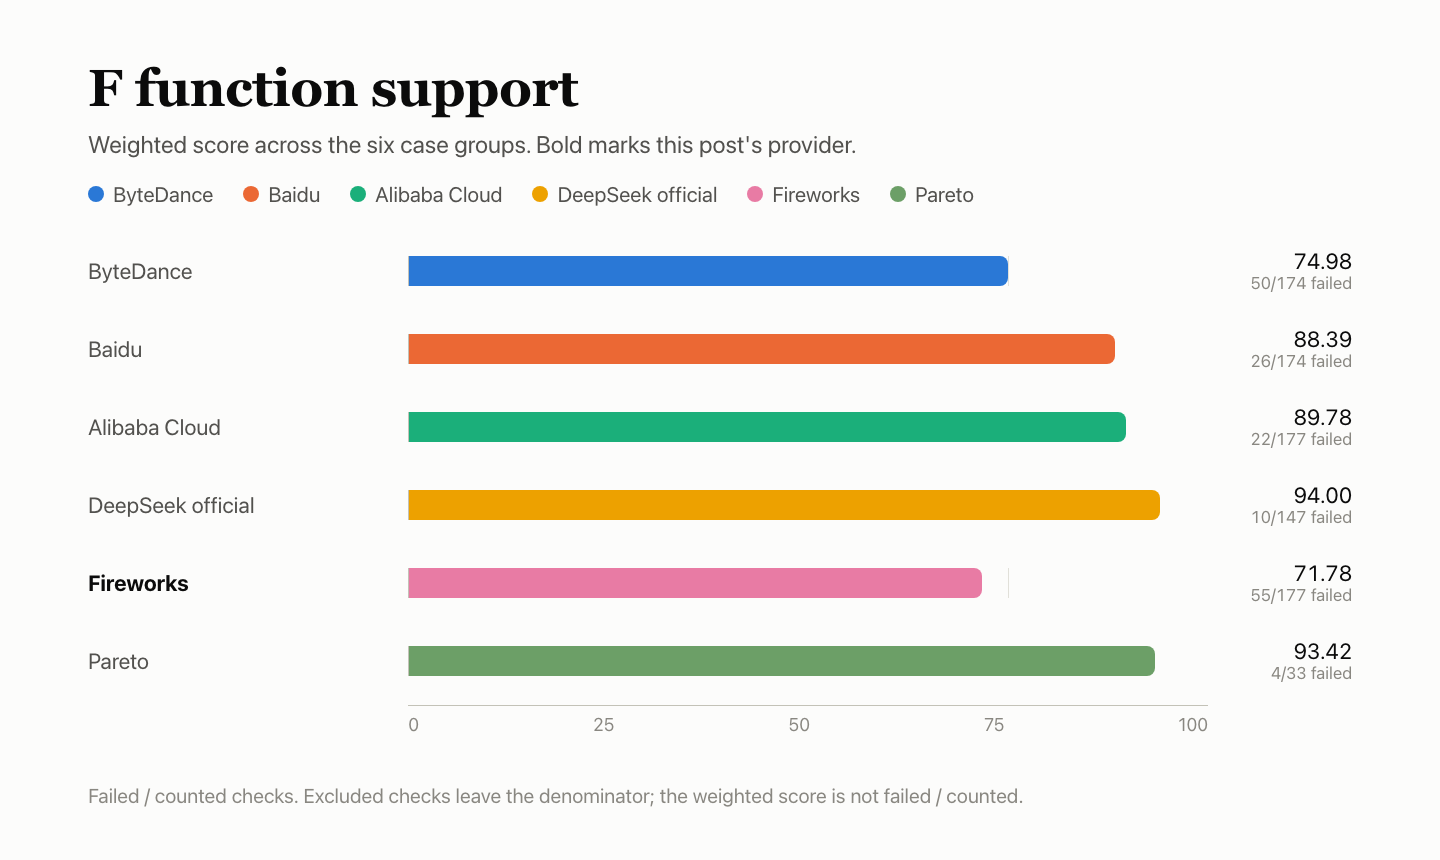
| Provider | Passed | Failed | Excluded | Weighted score |
|---|---|---|---|---|
| ByteDance | 124 | 50 | 6 | 74.98 |
| Baidu | 148 | 26 | 6 | 88.39 |
| Alibaba Cloud | 155 | 22 | 3 | 89.78 |
| DeepSeek official channel | 137 | 10 | 33 | 94.00 |
| Fireworks (this post) | 122 | 55 | 3 | 71.78 |
| Pareto | 29 | 4 | 147 | 93.42 |
P — response speed: 79.51
Each request carried about 10,000 input tokens and asked for about 1,100 output tokens of body text. In each of three windows, 30 requests ran at single concurrency and 30 at 10-way concurrency: 180 requests in all.
| Item | Detail |
|---|---|
| First body token (TTFA) | Median 1.63 s single, 1.64 s at 10-way |
| Generation speed (TPOT) | 3.24 ms/token single, 3.29 ms/token at 10-way |
| Effective throughput | 1,504.5 token/s at 10-way |
| Valid requests | 90/90 single, 89/90 at 10-way (window 3: 29/30); invalid: 1 body of only 1 token |
| Sub-scores | TTFA 54.91, TPOT 100.00, throughput 100.00; TTFA and TPOT take the lower tier, weighted 35% / 35% / 30%: response score 84.22 |
| P score | Response score 84.22 × 80% + cache K 60.68 × 20% = 79.51 |
Invalid requests are scored as infinite, so the medians in the table can be higher than valid-only medians. TPOT is estimated from streamed chunks, not measured per token on the hardware. Throughput is valid output tokens at 10-way concurrency divided by batch wall-clock time.
Compared with the other five
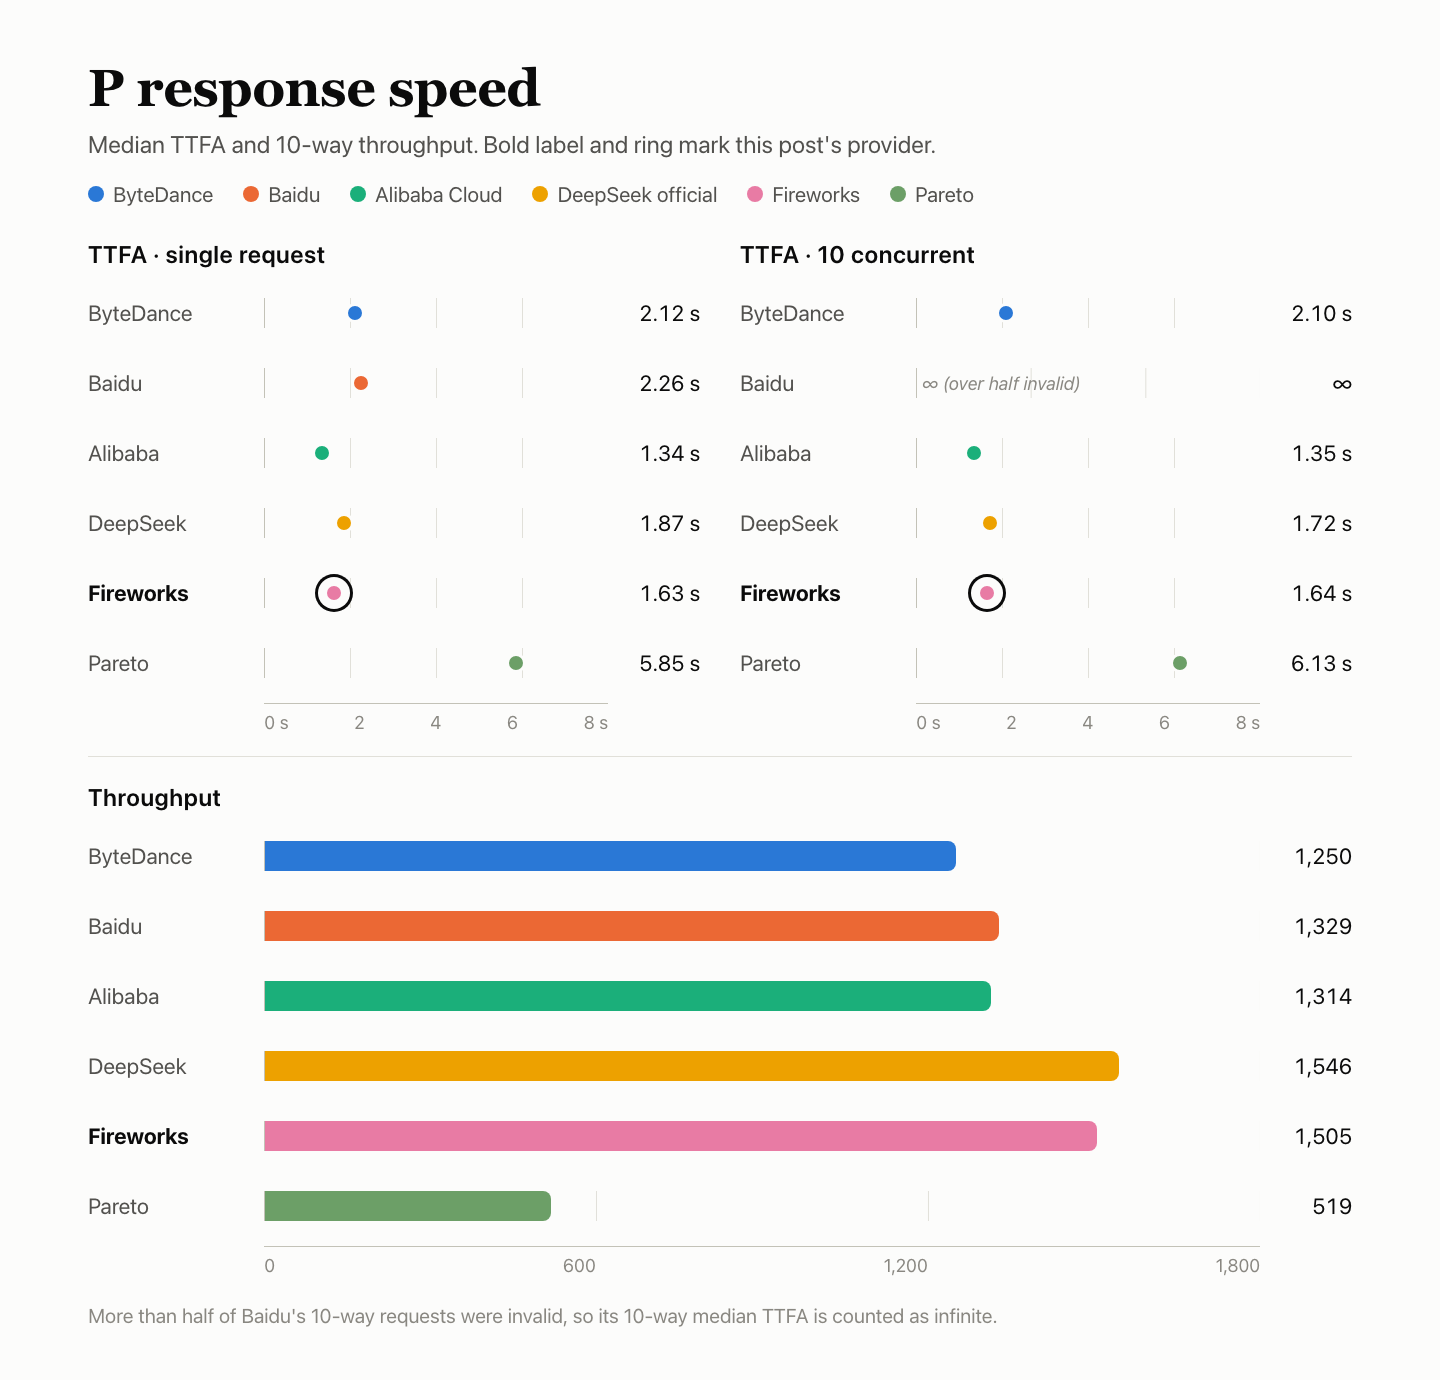
| Provider | Valid requests | TTFA single | TTFA 10-way | TPOT (slower) | Throughput tok/s | Response |
|---|---|---|---|---|---|---|
| ByteDance | 180/180 | 2.12 s | 2.10 s | 3.43 ms | 1,250 | 82.00 |
| Baidu | 118/180 | 2.26 s | ∞ | 50.00 ms | 1,329 | 30.00 |
| Alibaba Cloud | 180/180 | 1.34 s | 1.35 s | 4.69 ms | 1,314 | 85.88 |
| DeepSeek official channel | 165/180 | 1.87 s | 1.72 s | 2.84 ms | 1,546 | 83.08 |
| Fireworks (this post) | 179/180 | 1.63 s | 1.64 s | 3.29 ms | 1,505 | 84.22 |
| Pareto | 110/180 | 5.85 s | 6.13 s | 4.63 ms | 519 | 65.22 |
All six shared one machine, network and account. The three windows were scheduled provider by provider, so collection periods do not fully overlap; small differences should not be over-read. ∞ means more than half the requests were invalid, so the median counts as infinite.
K — cache: 60.68
Each group sends five requests. The first carries a fixed prefix of about 8k or 32k tokens and seeds the cache. Requests 2–4 keep the prefix and change only the final question, at gaps of 5 s, 30 s and 120 s. The fifth uses a new prefix as a cold control. Three windows × two lengths make 30 requests. K is the cache tokens read by hot requests divided by the tokens that should be reusable under the rules, with the two lengths weighted equally; K is 20% of P.
| Window | 1 · seed | 2 · +5 s | 3 · +30 s | 4 · +120 s | 5 · cold |
|---|---|---|---|---|---|
| 8k prefix · hot hits 3/9 · read 23,706 of 72,252 reusable · 32.81 | — | — | — | — | — |
| Window 1 | 0 | 7,900 | 0 | 7,900 | 0 |
| Window 2 | 0 | 7,906 | 0 | 0 | 0 |
| Window 3 | 0 | 0 | 0 | 0 | 0 |
| 32k prefix · hot hits 8/9 · read 255,212 of 288,261 reusable · 88.54 | — | — | — | — | — |
| Window 1 | 0 | 31,902 | 31,902 | 31,902 | 0 |
| Window 2 | 0 | 31,902 | 31,902 | 31,902 | 0 |
| Window 3 | 0 | 31,900 | 31,900 | 0 | 0 |
| K (8k and 32k weighted equally) | — | — | — | — | 60.68 |
Values are cache-read tokens reported by the server; “Not returned” means the field was absent from the response.
The 8k hot requests hit 3 of 9; the 32k hot requests hit 8 of 9. Cold requests read no cache, so hot and cold separate cleanly.
Compared with the other five
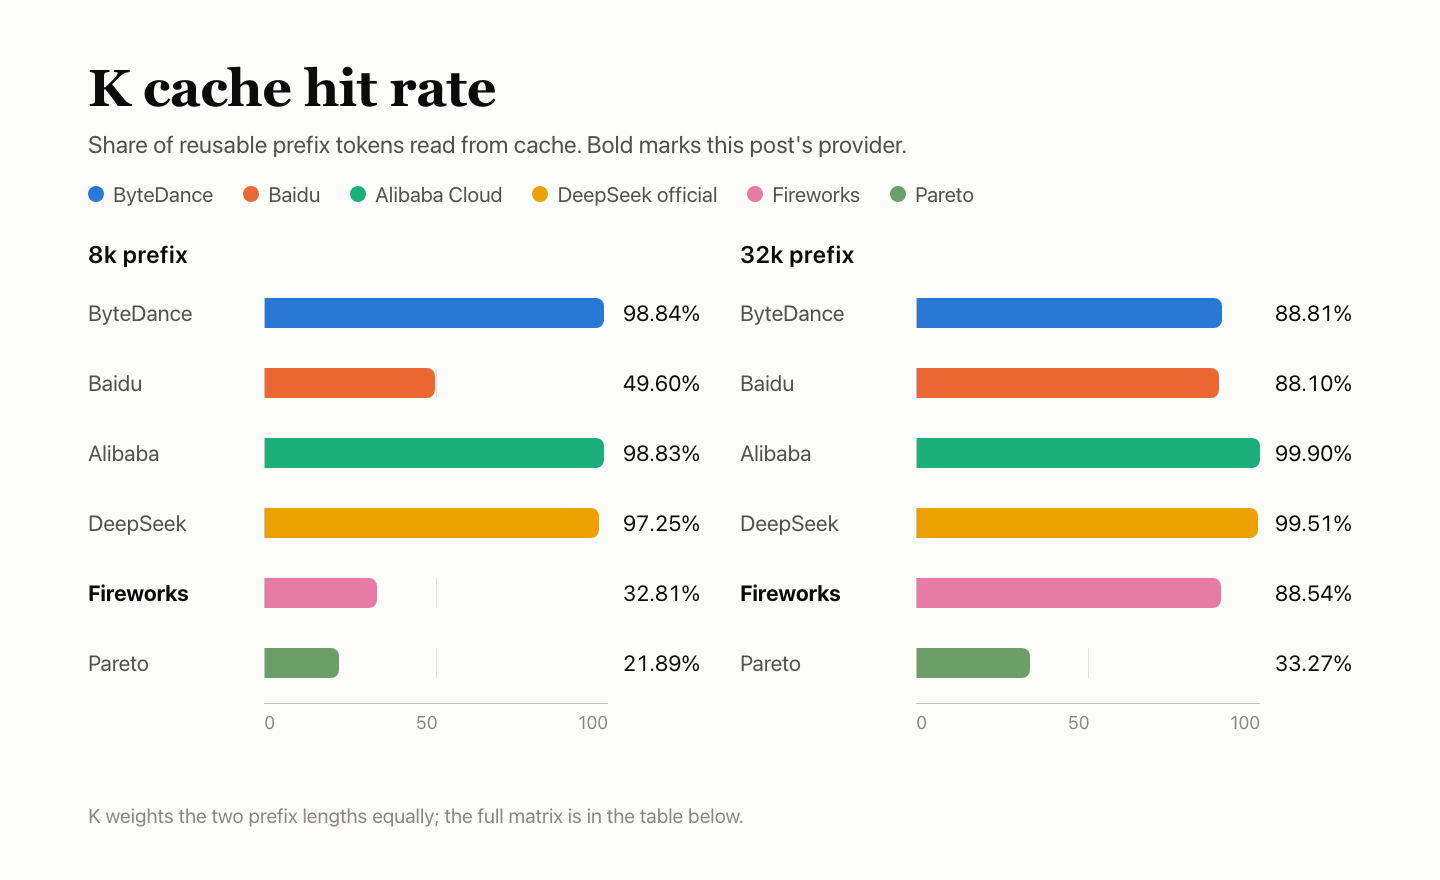
| Provider | 8k hits | 8k | 32k hits | 32k | K |
|---|---|---|---|---|---|
| ByteDance | 9/9 | 98.84 | 8/9 | 88.81 | 93.83 |
| Baidu | 5/9 | 49.60 | 8/9 | 88.10 | 68.85 |
| Alibaba Cloud | 9/9 | 98.83 | 9/9 | 99.90 | 99.37 |
| DeepSeek official channel | 9/9 | 97.25 | 9/9 | 99.51 | 98.38 |
| Fireworks (this post) | 3/9 | 32.81 | 8/9 | 88.54 | 60.68 |
| Pareto | 2/9 | 21.89 | 3/9 | 33.27 | 27.58 |
R — service stability: 100
The 300 requests fall into four types: short text, long input, tool calls and multi-turn history. They ran at single concurrency across three windows. Only whether the first attempt returned a valid, complete response is checked; answers are not graded and nothing is retried. Failures in the answer-quality and speed sections are counted in Q and P, not again in R.
| Request type | First-attempt success |
|---|---|
| Short text | 120/120 |
| 10k long input | 90/90 |
| Tool calls | 60/60 |
| Multi-turn history | 30/30 |
| Total · 95% interval 98.78%–100% | 300/300 |
All 300 requests returned a valid, complete response on the first attempt. R = 100 describes these 300 dedicated requests only; it does not mean the whole chain had no failures. The lower bound of the 95% interval is 98.78%: 300 successes out of 300 can only say the failure rate is likely below 1.22%.
Compared with the other five
| Provider | First-attempt success | 95% interval |
|---|---|---|
| ByteDance | 300/300 | 98.78%–100% |
| Baidu | 300/300 | 98.78%–100% |
| Alibaba Cloud | 300/300 | 98.78%–100% |
| DeepSeek official channel | 300/300 | 98.78%–100% |
| Fireworks (this post) | 300/300 | 98.78%–100% |
| Pareto | 300/300 | 98.78%–100% |
R covers only these 300 dedicated requests; failures in the answer-quality and speed sections are recorded in Q and P and are not counted again in R.
FAQ
What does Q 41.42 cover?
BFCL, HLE and AA-LCR pooled over 4,240 scored question-instances: 1,756 correct, 41.42%, with a 95% interval of 39.13%–43.59%. The gap to the official channel is −1.04 points (−2.14 to +0.05), not distinguishable.
Why did both stop cases fail?
A request with a stop sequence returned an empty body in all three windows, while the same input without stop returned normal output. It happened in both the streaming stop case and the output-constraints stop case.
Why did the APB v2 parameter-contract check fail?
In the separate APB v2 parameter-contract check, Fireworks still returned thinking content and still reported reasoning tokens, so those F cases failed. The contract check belongs to F only; Q, P, K and R used one shared request configuration.
Why is a 10k input reported as 10,026 tokens?
The 10k case reported 10,026 against a native 10,000, and the within-limit, 32k and 100k cases failed for the same reported count. Even the no-tools control misreported input tokens, and an 8-token input was reported as 34.
Why did 8k hit 3 of 9 while 32k hit 8 of 9?
Both lengths used the same five-request design and the session-affinity settings from Fireworks' documentation. The difference is in the server-reported reads: 8k hit only in windows 1 and 2, while 32k hit in all three windows.
What does R 100 cover?
300 dedicated requests, all valid and complete on the first attempt; the lower bound of the 95% interval is 98.78%. Failures in the Q and P runs are not counted in R.
Keep reading: the DeepSeek V4.1 Flash series
- ByteDance, like Fireworks, failed the APB v2 parameter-contract check and reported 10,026 tokens for a 10k input: ByteDance DeepSeek V4.1 Flash review: answers indistinguishable from official, input counts don't match.
- Baidu's 8k cache hit 5 of 9, with 3 request failures: Baidu DeepSeek V4.1 Flash review: tool calling on par with official, frequent no-available-channel pulls down answer quality and speed.
- Alibaba Cloud's hot requests hit 18 of 18, for K 99.37: Alibaba Cloud DeepSeek V4.1 Flash review: 1.34s first body token, all 18 hot requests hit cache, answers indistinguishable from official.
- The official channel is the Q baseline used here, with F 94.00: DeepSeek official channel DeepSeek V4.1 Flash review: comparison baseline, 15 invalid requests at single concurrency.
- Pareto also returned an empty body on streaming stop requests, and its 8k cache hit 2 of 9: Pareto DeepSeek V4.1 Flash review: only 5 hits in 18 hot requests, answers indistinguishable from official.
Sources
- DeepSeek V4.1 Flash 1017 model page (AIHubMix)
- AIHubMix Provider Benchmark Standard v2.0 (AIHubMix docs)
- Quick start (AIHubMix docs)
- Models (AIHubMix)
- DeepSeek API documentation (DeepSeek)